What Is Dynamic Data Replicator (DDR)? SAP Test Data Management Explained
What Is Dynamic Data Replicator (DDR)? SAP Test Data Management Explained
Dynamic Data Replicator (DDR) is Enterprise Data Insight's selective SAP test data management platform for delivering relevant, secure and governed data into non-production environments. Instead of making every DEV, QA, training, sandbox or S/4HANA requirement depend on another full production copy, DDR is designed to move the data required for the scenario together with the related SAP business context needed to use it.
Replicate selected SAP data for the scenario instead of transferring an entire production-sized dataset every time.
Include the related records, documents and dependencies required to make the selected data usable in the target.
Apply approved scrambling and controlled access so production-like data can be used more safely outside production.
Turn recurring data movement into a repeatable service with scheduling, validation, monitoring and operational control.
What Is Dynamic Data Replicator (DDR) in SAP?
Dynamic Data Replicator (DDR) is a selective SAP data replication and test data management platform from Enterprise Data Insight. It helps organisations deliver only the SAP data required for a non-production use case, preserve the related business dependencies, protect sensitive information and repeat the delivery through a controlled, validated process.
- DDR is designed to move the data required for a scenario rather than automatically copying an entire production-sized dataset.
- Selected SAP data must remain usable, so related records and business context form part of the delivery model.
- Security is built into the approach through data minimisation, approved scrambling and controlled access.
- Full system copies still have a role when broad production-scale volume or complete landscape state is genuinely required.

What Is Dynamic Data Replicator?
Dynamic Data Replicator, or DDR, is Enterprise Data Insight’s platform for selective SAP data replication and test data management. Its purpose is straightforward: give non-production teams the business data they need without automatically copying everything that exists in production.
Traditional SAP refresh models often start with the system. A team asks for a DEV, QA, training or project environment, and the response is to create or refresh that environment from a broad production copy. DDR starts from a different question: what data is required for this specific business or technical purpose?
That difference matters. A developer reproducing a pricing defect may need a particular sales document and its related customer, material, plant, pricing and document-flow context. A training team may need a realistic but protected dataset for selected business processes. A project team may need a controlled slice of data for one company code, plant, date range or programme phase. DDR is designed to support that selective approach.
Entity note: Dynamic Data Replicator is developed by Enterprise Data Insight as part of its SAP data management and non-production data capabilities.
DDR addresses the gap between a small non-production data requirement and a large system-refresh operation. It gives SAP teams a selective option when a complete production copy would move more data, expose more information or require more operational effort than the use case needs.
For related capabilities, explore Dynamic Data Replicator for SAP, SAP test data management with DDR and Enterprise Data Insight's broader approach to controlled non-production data delivery.
Why Copying Everything Is Not Always the Best Answer
Full SAP system copies remain valuable when a test or project genuinely requires broad production-scale data. The issue appears when the same full-copy approach is used for every requirement, regardless of how much of the copied information will actually be used.
That can create a mismatch between the size of the technical operation and the size of the business need. A small defect-reproduction scenario may wait for a large refresh. A training environment may inherit data that has no relevance to its exercises. A sandbox may contain far more sensitive production information than users require. A QA team may receive current data only when a major refresh window becomes available.
DDR is designed to introduce another option: retain full refreshes where they are justified, but use selective replication when a narrower and more relevant dataset can meet the requirement. This makes the data-delivery model more proportional to the actual use case.
From Source Systems Through DDR to Fit-for-Purpose Targets
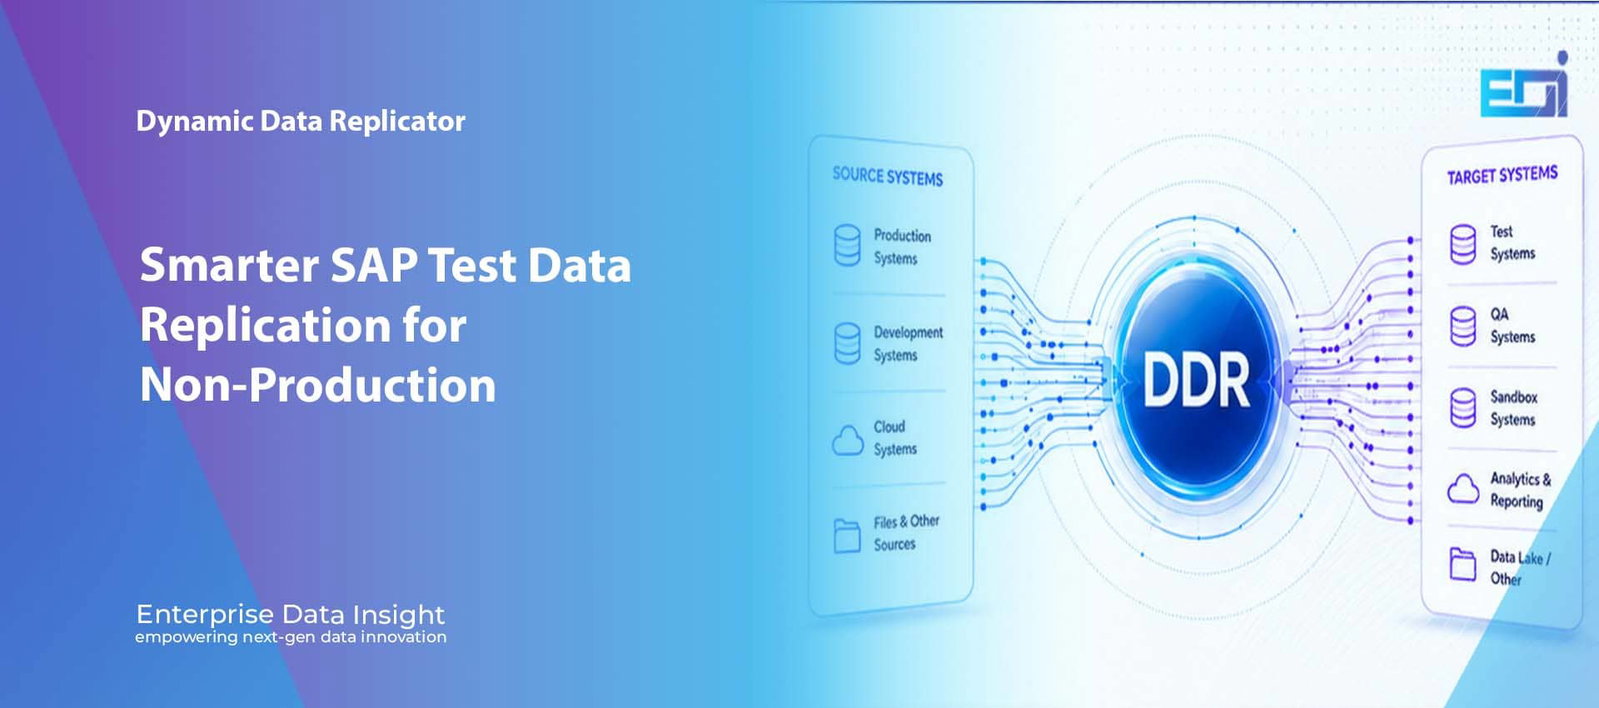
DDR operates as a controlled data-movement layer between source and target environments. Source data can originate from production systems, development systems, cloud environments, files or other approved sources. Targets can include test systems, QA systems, sandboxes, analytics and reporting environments, data lakes or other approved destinations.
Selective Replication: Move Only the Data Required for the Scenario
The first DDR principle is selective replication. Instead of assuming the target needs everything, the data request can be narrowed to the scope that serves the business purpose. That scope might be a business object, an organisational unit, a time slice, a set of records or another controlled selection supported by the implementation.
This changes the economics and operating model of SAP test data. The useful question becomes less about how quickly another entire source can be reproduced and more about how efficiently the required business scenario can be delivered to the team that needs it.
Selective replication also allows different targets to be treated differently. A development lane may need a focused defect scenario. QA may need broader regression coverage. Training may need realistic but carefully curated transactions. A sandbox may need enough data for exploration without inheriting the entire production estate.
Dependency-Aware Data: A Record Is Only Useful When Its Context Comes With It
Moving fewer records is only valuable if the target dataset still works. SAP business processes are connected: transactional data depends on master data, organisational structures, document relationships and other business context. Copying an isolated record without the information it relies on can create a technically successful transfer but a practically unusable test scenario.
DDR is therefore designed around dependency awareness. The selected business data is treated as part of a wider relationship graph rather than as an independent row in a table. The aim is to include the related records required to preserve meaningful context in the target.
This is one of the most important distinctions between simple data movement and usable test-data delivery. The result should not merely be “data arrived”; it should be “the requested business scenario can be used for the purpose for which it was requested.”
Secure by Design: Protect Sensitive Information Before It Spreads Across Non-Production
Non-production environments often serve larger and more varied user populations than production. Developers, testers, support teams, project resources, trainers and external partners may all require access to realistic data, but they do not necessarily need access to real sensitive production values.
DDR is designed to combine selective movement with data protection. Approved scrambling rules and controlled access can be incorporated into the delivery process so that sensitive information is protected as part of the workflow rather than treated as an afterthought.
Selective replication supports the same objective from another direction: if a scenario does not require a piece of production data, the safer approach is often not to move it at all. Data minimisation and data protection work together.
Automated and Repeatable: Turn Refresh Work Into a Reusable Data Service
A one-off selective copy may solve a single problem. The larger operational value comes when approved data scenarios can be repeated consistently. DDR is designed to support workflow, scheduling and monitoring so that recurring refresh needs can be standardised rather than rebuilt manually each time.
For a QA team, that could mean refreshing a defined regression dataset on a controlled schedule. For development, it could mean rerunning a known defect scenario after code changes. For a project team, it could mean repeating a selected organisational or time-based data movement across multiple test cycles.
The objective is a more predictable operating model: the organisation defines the scope and controls once, then executes the approved pattern repeatedly with visibility over what happened.
Validated and Governed: Speed Without Losing Control
Faster access to data does not remove the need for governance. In fact, a selective and repeatable service needs clear controls because data can be requested and moved more frequently than under an occasional full-refresh model.
DDR is designed to support audit visibility, consistency and control around the replication process. A mature operating model should be able to answer who requested the data, what source and target were used, what scope was selected, which protection rules applied, whether the execution completed as expected and whether the resulting dataset was validated.
That evidence matters operationally as well as for assurance. When a test-data issue occurs, teams need to understand exactly what was delivered and under which rules rather than relying on an informal manual process.
Built for SAP Business Processes, Not Just Generic Database Movement
SAP landscapes contain complex relationships between business objects, organisational structures, master data and transactions. A useful test-data platform therefore needs to think beyond moving tables from one database to another.
DDR is positioned as a selective SAP data platform designed for the realities of enterprise SAP environments and business processes. Its value comes from combining scope selection, related-data handling, security, automation and governance into a process that is aimed at producing usable target data.
That makes DDR relevant not only to routine system refresh activity, but also to development, testing, training, support, project delivery and S/4HANA transformation programmes where the right data must be available at the right time.
One Platform, Multiple SAP Non-Production Use Cases
The same selective approach can support very different consumers across an SAP landscape. The required scope, frequency and protection policy may vary by target, but the operating principle remains consistent: deliver enough relevant data to serve the purpose without automatically moving everything.
Provide focused business scenarios so developers can test changes against more realistic context earlier.
Refresh high-value regression and integration scenarios with repeatable, controlled data.
Create practical exercises using production-like context while protecting sensitive values.
Give teams useful business data for experimentation without making every sandbox production-sized.
Deliver targeted datasets for migration, release, remediation and programme test cycles.
Support test, validation and transformation activities with fit-for-purpose data between major cycles.
DDR Connects the Data Requirement to the Target That Needs It
The DDR model is not limited to a single source-to-single-target refresh pattern. The supplied architecture illustrates production, development, cloud systems, files and other sources feeding through DDR into test, QA, sandbox, analytics, reporting, data-lake and other target environments.
This matters because modern SAP estates are rarely a simple production-to-QA chain. Organisations may have parallel project landscapes, temporary test systems, analytics consumers, cloud services and multiple delivery teams operating at different speeds.
A selective replication layer gives the organisation a consistent way to decide what can move, where it can move, how it must be protected and how the resulting delivery is controlled.
Why Enterprises Choose a Selective DDR Approach
The business case for DDR is not simply “copy less data.” The broader value is reducing the operational friction between a team asking for relevant SAP data and that team receiving a usable, protected and governed dataset.
Use DDR when the target needs relevant SAP business data but does not require the complete source system. The platform is designed to reduce unnecessary data movement, improve test-data relevance, protect sensitive values and make approved delivery patterns repeatable.
Move less data. Transfer the data required for the scenario rather than defaulting to the complete source. This is especially useful when the business need is narrow compared with the size of production.
Reduce refresh complexity. Standardise recurring data-delivery patterns so teams are not forced to treat every request as another large infrastructure event.
Protect sensitive information. Combine selective scope with scrambling and controlled access so non-production users receive what they need without unnecessarily expanding exposure.
Provide more relevant test data. Focus each target on the scenarios that matter to its purpose rather than relying on whatever happens to be present after the last broad refresh.
Support faster project delivery. When teams can obtain the right data more predictably, data preparation is less likely to become a bottleneck between development, test and project cycles.
Example: Reproduce a Business Issue Without Refreshing the Whole SAP System
Assume a support or development team needs to reproduce a problem affecting one business transaction. The issue depends on the document itself plus related customer, material, organisational and historical context. The target DEV environment does not currently contain the scenario.
A traditional response may be to wait for the next broad refresh or rebuild the scenario manually. With a selective model, the request begins with the affected business object and target environment. DDR then applies the approved scope, includes the related context needed for the scenario, protects sensitive values, moves the data and validates the delivery.
The team needs enough context to recreate the behaviour, not an entire production database.
The selected scenario is delivered into the environment where the change will be investigated or tested.
Dependencies are included according to the approved business-data design.
The request is treated as a governed data service rather than an ad-hoc manual copy.
DDR Does Not Eliminate Full System Copies — It Gives SAP Teams Another Option
There are scenarios where a broad or production-scale system copy remains appropriate. Performance testing, certain migration rehearsals, major integration cycles or exercises that require the complete state of the landscape may justify a larger refresh. DDR should be understood as a complementary model that allows selective delivery when a full copy is unnecessary.
Choose based on the test purpose. Use a full copy when the requirement genuinely needs broad production-scale data or a complete landscape state. Use a selective DDR approach when a defined business scenario can be served by a smaller, relevant and governed dataset.
| Requirement | Full System Copy | Selective DDR Approach |
|---|---|---|
| Production-scale performance or volume test | Often appropriate where broad scale is required. | May complement the environment but is not a substitute for required production-scale volume. |
| Reproduce one business defect | Can be disproportionate to the size of the request. | Designed to deliver the selected scenario and related context. |
| Refresh a focused QA regression set | Moves much more data than the regression pack may need. | Can target the approved data needed for the test scope. |
| Training or sandbox requirement | May expose more production data than users require. | Supports curated scope plus protection controls. |
| Repeated project test cycles | Can make data preparation dependent on major refresh windows. | Supports a repeatable, schedulable selective-delivery pattern. |
From “Refresh the System” to “Deliver the Data the Team Needs”
The most important shift introduced by DDR is conceptual. Non-production data stops being treated only as a by-product of a system refresh and becomes a service that can be requested, scoped, protected, delivered and validated according to purpose.
That creates a more flexible SAP operating model. Large refreshes can remain part of the landscape strategy, while targeted deliveries handle the many smaller requirements that occur between them. Development can receive relevant scenarios earlier. QA can maintain useful test packs. Training can work with curated data. Project teams can repeat approved datasets across multiple cycles.
In that model, the question is no longer simply “When is the next refresh?” It becomes “What is the minimum relevant, secure and governed dataset required to achieve this outcome?”
That is the role DDR is designed to play: a selective SAP data platform built for speed, control and usable outcomes.
Dynamic Data Replicator FAQ
What is DDR in SAP?
DDR stands for Dynamic Data Replicator. It is Enterprise Data Insight’s selective SAP data replication and test-data-management platform, designed to move the data required for a non-production scenario together with the related context needed to use it.
Is DDR the same as a full SAP system copy?
No. A full system copy broadly reproduces a source environment. DDR is designed for selective replication, allowing the target dataset to be scoped to the business or technical requirement. Full copies can still be used where broad scale is genuinely required.
What environments can DDR support?
The supplied DDR model includes development, test, QA, training, sandbox, project, analytics and other non-production or downstream target scenarios. The exact implementation depends on the customer’s SAP landscape and approved architecture.
How does DDR keep selected SAP data usable?
DDR is designed to be dependency-aware, meaning the selected data can be delivered with the related records and business context required to preserve a usable scenario in the target environment.
How does DDR protect sensitive production data?
DDR can combine selective scope with approved scrambling and controlled access. The objective is both to avoid moving unnecessary information and to protect sensitive values that are required for the target scenario.
Can DDR be automated?
Yes. Automation and repeatability are core principles of the DDR model, including workflow, scheduling, monitoring and validation so approved data-delivery patterns can be rerun consistently.
Where does DDR add value during S/4HANA programmes?
S/4HANA programmes often need representative data across development, testing, migration, regression, training and project cycles. DDR can support selective and repeatable data delivery between major refresh or migration events where the use case does not require a complete production-scale dataset.
Does DDR replace SAP system refreshes?
No. DDR provides a selective alternative for use cases that do not need a complete source-system copy. Full refreshes remain appropriate when the test genuinely requires broad production-scale volume, complete landscape state or a large migration rehearsal.
What is selective SAP data replication?
Selective SAP data replication means moving a defined subset of SAP business data to a target environment instead of copying the entire source. A usable selective dataset should include the related records and dependencies required for the requested business scenario.
Smarter. More Selective. More Secure.
Dynamic Data Replicator is designed to help SAP teams move from heavyweight, one-size-fits-all refreshes toward fit-for-purpose non-production data. Select the right data, preserve its business context, protect sensitive information, validate the outcome and repeat the process through a controlled operating model.